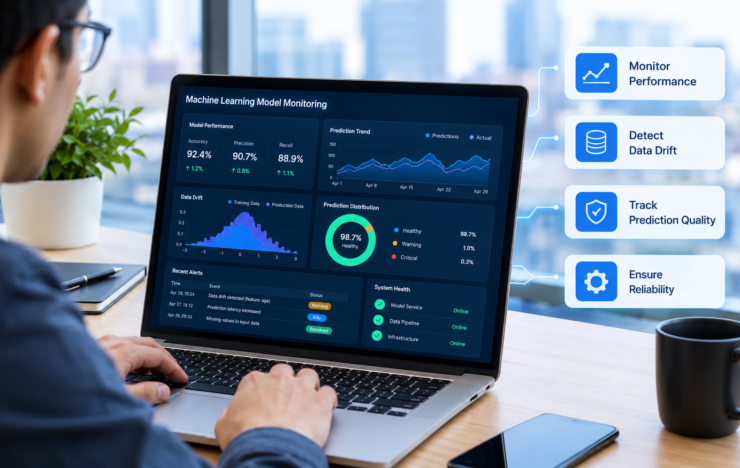
Building a machine learning model is only one part of a successful machine learning project. Once a model starts making predictions in a real business environment, its performance can change as customer behavior, market conditions, data sources, and business processes evolve.
A model that performs well during testing may not deliver the same results several months later. For example, a retail forecasting model trained on historical sales may struggle when product demand changes significantly. A customer classification model may also become less useful when the business introduces new services or attracts a different audience.
This is why machine learning model monitoring matters. It helps businesses identify changes in data, evaluate prediction quality, detect operational problems, and decide when a model needs attention.
In this guide, we explain what machine learning model monitoring involves, which metrics businesses should track, how to recognize common problems, and how to create a practical monitoring process.
What Is Machine Learning Model Monitoring?
Machine learning model monitoring is the process of checking a deployed model to determine whether it continues to operate as expected.
During development, teams usually evaluate a model using historical data and separate test datasets. After deployment, the model receives new inputs from actual users, transactions, products, or business operations. These inputs may differ from the examples used during training.
Monitoring helps teams examine several aspects of a deployed system:
- Whether incoming data follows expected formats and ranges.
- Whether production data differs significantly from training data.
- Whether predictions are changing unexpectedly.
- Whether the model continues to meet its business objectives.
- Whether prediction requests are slow, failing, or consuming unexpected resources.
Monitoring does not automatically improve a model. Instead, it provides information that helps a team investigate problems and decide what action is appropriate.
Why Can Machine Learning Models Become Less Reliable?
A machine learning model learns patterns from the data used during development. When the environment changes, those patterns may become less useful.
1. Changes in Customer Behavior
Customer preferences and purchasing habits can change over time. A model trained on previous buying patterns may become less effective when customers begin choosing different products or channels.
For example, an online retailer may use machine learning to estimate demand for seasonal products. If customer preferences shift, the model’s forecasts may become less accurate even if the software continues running without errors.
2. Changes in Input Data
A model may depend on specific fields, formats, or ranges. If an upstream application changes its data structure, the model may receive missing values, unexpected categories, or incorrectly formatted records.
Imagine a sales prediction system that expects product prices in one currency but begins receiving values converted from another currency without a corresponding indicator. Its predictions could become unreliable even though the model itself has not changed.
3. Data Drift and Changing Relationships
Data drift generally refers to changes in the distribution of incoming data over time. For instance, a model may begin receiving a larger proportion of orders from a new customer segment.
A related problem occurs when the relationship between input data and the outcome changes. A pattern that previously predicted customer cancellations may no longer be as useful after the company changes its subscription plans or support process.
These changes do not always mean that a model has failed. They are signals that the team should investigate whether its assumptions and performance remain appropriate.
4. Operational Problems
A model can also encounter technical issues unrelated to prediction quality. These include failed data pipelines, slow responses, service interruptions, increased infrastructure costs, and missing records.
A reliable monitoring process should cover both the model’s predictions and the surrounding system.
The Main Metrics to Monitor
There is no single metric that works for every machine learning application. The appropriate measurements depend on the task and the consequences of an incorrect prediction.
Data Quality
Check whether incoming records contain the fields and formats expected by the model.
Useful measurements include missing-value rates, invalid values, unexpected categories, duplicate records, and changes in input distributions.
For example, a demand forecasting model may need valid dates, product identifiers, prices, and historical sales. Missing or inconsistent information can affect the quality of its predictions.
Prediction Quality
When actual outcomes become available, compare them with the model’s predictions.
For a forecasting model, a business might measure the difference between predicted and actual demand. For a classification model, it may examine precision, recall, and the types of errors the model makes.
The choice of metric matters. A model used to flag potentially fraudulent transactions should not be evaluated only by overall accuracy, because genuine transactions may greatly outnumber fraudulent ones.
Business Performance
Technical metrics do not always show whether the model helps the business.
A forecasting system should be evaluated in relation to inventory planning, avoidable shortages, or other relevant operational outcomes. A customer service classification model might be assessed through routing quality, handling time, and the number of urgent requests incorrectly categorized.
These measures help the organization determine whether the model continues to provide practical value.
Latency and Availability
Latency measures how long a model takes to return a prediction. Availability reflects whether the service is accessible when needed.
A model that produces good predictions but regularly responds too slowly may not be suitable for its intended workflow.
Businesses should define acceptable response times, monitor failures, and create procedures for handling service interruptions.
Cost and Resource Usage
Monitor the infrastructure, computing resources, and service usage associated with running the model.
A system may become more expensive as request volumes increase or data processing requirements grow. Monitoring helps teams identify unusual usage and assess whether the ongoing costs remain justified.
How to Set Up a Machine Learning Monitoring Process
A practical monitoring system does not have to begin with a complicated technical platform. Start with the risks and business requirements of the specific model.
Step 1: Record a Baseline
Before deployment, document how the model performs during testing.
Record the evaluation metrics, characteristics of the test data, known limitations, and expected operating conditions. This baseline gives the team something meaningful to compare against after deployment.
For example, a forecasting project might record its typical prediction error across different product categories rather than relying on one overall score.
Step 2: Define Monitoring Rules
Choose which measurements matter and establish thresholds that should trigger investigation.
A missing-value rate above an agreed limit might indicate a broken data pipeline. A significant increase in prediction error could indicate that the model needs to be reviewed.
Thresholds should reflect the application. A small variation may be acceptable for one use case but important for another.
Step 3: Collect Production Data and Logs
Record appropriate information about model inputs, outputs, response times, errors, and relevant outcomes.
Data collection must follow applicable privacy, security, and retention requirements. Avoid collecting sensitive information that is unnecessary for monitoring.
The team should also determine how actual outcomes will be obtained. Some tasks, such as forecasting sales, may have measurable results after a period of time. Others may require feedback from users or a later review process.
Step 4: Create Alerts for Important Problems
Monitoring becomes more useful when it helps the team respond to issues promptly.
Alerts can be configured for conditions such as repeated prediction failures, unexpected input formats, deteriorating model quality, or unusual service costs.
Avoid creating so many alerts that employees begin ignoring them. Prioritize conditions that require action and assign responsibility for investigating each type of problem.
Step 5: Investigate Before Retraining
When a metric changes, retraining the model immediately is not always the correct response.
First, determine whether the issue comes from incorrect data, a software change, a genuine shift in business conditions, or a weakness in the model.
If an upstream system has started sending incorrect values, retraining on those values could make the situation worse. Correcting the data pipeline may be the more appropriate solution.
Step 6: Test and Deploy Improvements Carefully
If the model needs an update, prepare a new version and evaluate it before replacing the current one.
Use suitable validation data, compare the new version against the existing model, and check that the change addresses the identified problem.
For important applications, keep a rollback plan so the team can restore a previous version if the updated model behaves unexpectedly.
Step 7: Review Monitoring Regularly
Monitoring should be an ongoing responsibility, not a task performed only after a complaint.
Review alerts, model performance, data quality, operational costs, and business outcomes at a frequency appropriate for the application. High-volume or high-impact systems may need more frequent checks than an internal tool used occasionally.
The objective is to identify problems early enough to investigate them before they create substantial business disruption.
A Practical Example: Monitoring a Retail Demand Forecasting Model
Consider a retailer that uses machine learning to forecast weekly product demand. The forecasts help its purchasing team decide how much stock to order.
Initially, the model performs reasonably well. Several months later, the business introduces new product categories and changes its promotional strategy.
The monitoring process begins to reveal that forecast errors have increased for some products. At the same time, the distribution of incoming product categories differs from the original training data.
The team investigates and finds that new products are being grouped incorrectly in the data pipeline. The model was not designed to interpret the new categories in the same way as the existing ones.
Instead of immediately retraining the entire model, the team corrects the categorization process, tests the updated data, and evaluates the forecasts again.
This example illustrates why monitoring needs to cover the full system. A prediction problem may originate in data preparation, software integration, or changing business conditions rather than the model algorithm alone.
Common Mistakes in Model Monitoring
Monitoring Only During Development
A successful test result does not guarantee that a model will continue to perform well in production.
Better approach: Establish monitoring before deployment and continue reviewing the model after it begins receiving real-world data.
Tracking Technical Metrics Without Business Outcomes
A model can meet its technical targets while failing to improve the process it was designed to support.
Better approach: Connect model metrics to operational measures, such as fewer avoidable stock shortages, more effective request routing, or reduced manual review time.
Retraining Too Frequently
Regular retraining may sound like a simple solution, but it can introduce new errors if recent data is incomplete, unrepresentative, or incorrectly labeled.
Better approach: Define evidence-based conditions for retraining and validate every new model version before deployment.
Ignoring Data and Integration Problems
Unexpected predictions may be caused by incorrect data formats, missing values, or failed integrations rather than a weakness in the algorithm.
Better approach: Monitor the entire data and prediction pipeline, not just the final model output.
Failing to Assign Responsibility
Alerts are ineffective if nobody is responsible for reviewing them or deciding what to do next.
Better approach: Assign ownership for monitoring, incident investigation, model updates, and approval of important changes.
What Tools Can Businesses Use for Model Monitoring?
The right monitoring approach depends on the model, infrastructure, team skills, and operating requirements.
Businesses may combine several types of tools:
- Cloud machine learning platforms: May offer integrated monitoring for supported models and deployments.
- Data quality tools: Help identify missing, invalid, or unexpected input values.
- Logging and observability platforms: Track application errors, response times, availability, and resource usage.
- Custom dashboards: Combine model performance, business indicators, and operational information in one place.
For example, Google Cloud documents monitoring capabilities for identifying changes in model input data and prediction distributions. The appropriate features and setup depend on the platform and model type.
Before choosing a tool, check supported model formats, integration requirements, data access controls, alerting options, pricing, and the level of technical expertise needed to operate it.
A small project may need only structured logs and periodic evaluation. A business-critical model operating at high volume may require automated alerts, detailed dashboards, and a formal incident-response process.
How to Evaluate a Machine Learning Service Provider
If your business does not have an in-house machine learning team, an external specialist may help design, deploy, or monitor a model.
Before selecting a provider, ask:
- How will the model’s performance be measured before deployment?
- Which data quality checks will be included?
- How will data drift and prediction errors be detected?
- Who will investigate alerts and resolve technical problems?
- What are the expected infrastructure and maintenance costs?
- How will model updates be tested and approved?
- Can the business access its data, logs, and model documentation?
- What happens if the model stops meeting its intended performance targets?
Ask the provider to explain the monitoring plan using your actual business requirements. A proposal should distinguish between capabilities already included in the service and work that would require additional development or fees.
For businesses comparing AI and machine learning specialists, the AIML Marketplace directory can be a starting point for discovering potential providers. Verify each provider’s services, experience, and terms directly before making a decision.
Machine learning models need ongoing attention after deployment. Changes in data, customer behavior, business processes, and infrastructure can affect the reliability and value of their predictions.
A practical monitoring process combines data quality checks, prediction evaluation, operational alerts, and business performance measurements. When problems appear, teams should investigate their causes before deciding whether to correct the data, adjust the workflow, or update the model.
For businesses investing in machine learning, monitoring is an important part of responsible implementation. It helps turn a promising model into a system that can be evaluated, maintained, and improved over time.
The goal is not simply to keep a model running. It is to ensure that the model continues to serve its intended purpose and provides value under real operating conditions.
Frequently Asked Questions
It is the ongoing process of checking a deployed model’s input data, predictions, operational health, and business performance to identify problems and determine whether intervention is needed.
Data drift describes changes in the distribution of incoming data over time. If the new data differs substantially from the data used to develop the model, the model may need further evaluation.
The frequency depends on how quickly the data changes, how often the model is used, and the consequences of an incorrect prediction. Some systems need continuous automated checks, while others may be reviewed periodically.
No. Retraining should depend on evidence that the model needs updating, the availability of suitable new data, and the results of validation. Retraining without checking data quality can introduce additional problems.
Yes. A small business can begin with basic logging, periodic comparison of predictions with actual outcomes, and checks for missing or unexpected data. More sophisticated monitoring can be introduced as the system and its importance grow.
Model evaluation typically measures performance using a defined dataset during development or testing. Model monitoring examines the system after deployment and helps determine whether its behavior remains appropriate as real-world conditions change.
 Free Consultation call: your goals, timeline, and ballpark budget